Innovate not imitate!

Innovate not imitate!
Interested in the latest Growth hacks?

Welcome to our blog

Interested in the latest Growth hacks?

Welcome to our blog!

We want to help you start/manage and grow your business using innovative strategies and implementation. We have a passion for helping businesses and companies of various sizes see the same success that we have achieved.

Our skillsets are wide and varied, from business strategy, marketing, to online strategy. An increasing number of companies are turning to the internet and online media as a means to maximising their marketing reach and exposure. This is special area of focus for us and we do more than simple SEO strategies.

See our website for more: www.innovatetoaccelerate.com

Tuesday, 11 April 2017

Announcing the 2017 Local Search Ranking Factors Survey Results

Posted by Whitespark

Since its inception in 2008, David Mihm has been running the Local Search Ranking Factors survey. It is the go-to resource for helping businesses and digital marketers understand what drives local search results and what they should focus on to increase their rankings. This year, David is focusing on his new company, Tidings, a genius service that automatically generates perfectly branded newsletters by pulling in the content from your Facebook page and leading content sources in your industry. While he will certainly still be connected to the local search industry, he’s spending less time on local search research, and has passed the reins to me to run the survey.

David is one of the smartest, nicest, most honest, and most generous people you will ever meet. In so many ways, he has helped direct and shape my career into what it is today. He has mentored me and promoted me by giving me my first speaking opportunities at Local U events, collaborated with me on research projects, and recommended me as a speaker at important industry conferences. And now, he has passed on one of the most important resources in our industry into my care. I am extremely grateful.

Thank you, David, for all that you have done for me personally, and for the local search industry. I am sure I speak for all who know you personally and those that know you through your work in this space; we wish you great success with your new venture!

I’m excited to dig into the results, so without further ado, read below for my observations, or:

Click here for the full results!

Shifting priorities

Here are the results of the thematic factors in 2017, compared to 2015:

Thematic Factors

2015

2017

Change

GMB Signals

21.63%

19.01%

-12.11%

Link Signals

14.83%

17.31%

+16.73%

On-Page Signals

14.23%

13.81%

-2.95%

Citation Signals

17.14%

13.31%

-22.36%

Review Signals

10.80%

13.13%

+21.53%

Behavioral Signals

8.60%

10.17%

+18.22%

Personalization

8.21%

9.76%

+18.81%

Social Signals

4.58%

3.53%

-22.89%

If you look at the Change column, you might get the impression that there were some major shifts in priorities this year, but the Change number doesn’t tell the whole story. Social factors may have seen the biggest drop with a -22.89% change, but a shift in emphasis on social factors from 4.58% to 3.53% isn’t particularly noteworthy.

The decreased emphasis on citations compared to the increased emphasis on link and review factors, is reflective of shifting focus, but as I’ll discuss below, citations are still crucial to laying down a proper foundation in local search. We’re just getting smarter about how far you need to go with them.

The importance of proximity

For the past two years, Physical Address in City of Search has been the #1 local pack/finder ranking factor. This makes sense. It’s tough to rank in the local pack of a city that you’re not physically located in.

Well, as of this year’s survey, the new #1 factor is… drumroll please…

Proximity of Address to the Point of Search

This factor has been climbing from position #8 in 2014, to position #4 in 2015, to claim the #1 spot in 2017. I’ve been seeing this factor’s increased importance for at least the past year, and clearly others have noticed as well. As I note in my recent post on proximity, this leads to poor results in most categories. I’m looking for the best lawyer in town, not the closest one. Hopefully we see the dial get turned down on this in the near future.

While Proximity of Address to the Point of Search is playing a stronger role than ever in the rankings, it’s certainly not the only factor impacting rankings. Businesses with higher relevancy and prominence will rank in a wider radius around their business and take a larger percentage of the local search pie. There’s still plenty to be gained from investing in local search strategies.

Here’s how the proximity factors changed from 2015 to 2017:

Proximity Factors

2015

2017

Change

Proximity of Address to the Point of Search

#4

#1

+3

Proximity of Address to Centroid of Other Businesses in Industry

#20

#30

-10

Proximity of Address to Centroid

#16

#50

-34

While we can see that Proximity to the Point of Search has seen a significant boost to become the new #1 factor, the other proximity factors which we once thought were extremely important have seen a major drop.

I’d caution people against ignoring Proximity of Address to Centroid, though. There is a situation where I think it still plays a role in local rankings. When you’re searching from outside of a city for a key phrase that contains the city name (Ex: Denver plumbers), then I believe Google geo-locates the search to the centroid and Proximity of Address to Centroid impacts rankings. This is important for business categories that are trying to attract searchers from outside of their city, such as attractions and hotels.

Local SEOs love links

Looking through the results and the comments, a clear theme emerges: Local SEOs are all about the links these days.

In this year’s survey results, we’re seeing significant increases for link-related factors across the board:

Local Pack/Finder Link Factors

2015

2017

Change

Quality/Authority of Inbound Links to Domain

#12

#4

+8

Domain Authority of Website

#6

#6

-

Diversity of Inbound Links to Domain

#27

#16

+11

Quality/Authority of Inbound Links to GMB Landing Page URL

#15

#11

+4

Quantity of Inbound Links to Domain

#34

#17

+17

Quantity of Inbound Links to Domain from Locally Relevant Domains

#31

#20

+11

Page Authority of GMB Landing Page URL

#24

#22

+2

Quantity of Inbound Links to Domain from Industry-Relevant Domains

#41

#28

+13

Product/Service Keywords in Anchor Text of Inbound Links to Domain

-

#33

+17

Location Keywords in Anchor Text of Inbound Links to Domain

#45

#38

+7

Diversity of Inbound Links to GMB Landing Page URL

-

#39

+11

Quantity of Inbound Links to GMB Landing Page URL from LocallyRelevant Domains

-

#48

+2

Google is still leaning heavily on links as a primary measure of a business’ authority and prominence, and the local search practitioners that invest time and resources to secure quality links for their clients are reaping the ranking rewards.

Fun fact: "links" appears 76 times in the commentary.

By comparison, "citations" were mentioned 32 times, and "reviews" were mentioned 45 times.

Shifting priorities with citations

At first glance at all the declining factors in the table below, you might think that yes, citations have declined in importance, but the situation is more nuanced than that.

Local Pack/Finder Citation Factors

2015

2017

Change

Consistency of Citations on The Primary Data Sources

n/a

#5

n/a

Quality/Authority of Structured Citations

#5

#8

-3

Consistency of Citations on Tier 1 Citation Sources

n/a

#9

n/a

Quality/Authority of Unstructured Citations (Newspaper Articles, Blog Posts, Gov Sites, Industry Associations)

#18

#21

-3

Quantity of Citations from Locally Relevant Domains

#21

#29

-8

Prominence on Key Industry-Relevant Domains

n/a

#37

n/a

Quantity of Citations from Industry-Relevant Domains

#19

#40

-21

Enhancement/Completeness of Citations

n/a

#44

n/a

Proper Category Associations on Aggregators and Tier 1 Citation Sources

n/a

#45

n/a

Quantity of Structured Citations (IYPs, Data Aggregators)

#14

#47

-33

Consistency of Structured Citations

#2

n/a

n/a

Quantity of Unstructured Citations (Newspaper Articles, Blog Posts)

#39

-

-11

You’ll notice that there are many “n/a” cells on this table. This is because I made some changes to the citation factors. I elaborate on this in the survey results, but for your quick reference here:

  1. To reflect the reality that you don’t need to clean up your citations on hundreds of sites, Consistency of Structured Citations has been broken down into 4 new factors:
    1. Consistency of Citations on The Primary Data Sources
    2. Consistency of Citations on Tier 1 Citation Sources
    3. Consistency of Citations on Tier 2 Citation Sources
    4. Consistency of Citations on Tier 3 Citation Sources
  2. I added these new citation factors:
    1. Enhancement/Completeness of Citations
    2. Presence of Business on Expert-Curated "Best of" and Similar Lists
    3. Prominence on Key Industry-Relevant Domains
    4. Proper Category Associations on Aggregators and Top Tier Citation Sources

Note that there are now more citation factors showing up, so some of the scores given to citation factors in 2015 are now being split across multiple factors in 2017:

  • In 2015, there were 7 citation factors in the top 50
  • In 2017, there are 10 citation factors in the top 50

That said, overall, I do think that the emphasis on citations has seen some decline (certainly in favor of links), and rightly so. In particular, there is an increasing focus on quality over quantity.

I was disappointed to see that Presence of Business on Expert-Curated "Best of" and Similar Lists didn’t make the top 50. I think this factor can provide a significant boost to a business’ local prominence and, in turn, their rankings. Granted, it’s a challenging factor to directly influence, but I would love to see an agency make a concerted effort to outreach to get their clients listed on these, measure the impact, and do a case study. Any takers?

GMB factors

There is no longer an editable description on your GMB listing, so any factors related to the GMB description field were removed from the survey. This is a good thing, since the field was typically poorly used, or abused, in the past. Google is on record saying that they didn’t use it for ranking, so stuffing it with keywords has always been more likely to get you penalized than to help you rank.

Here are the changes in GMB factors:

GMB Factors

2015

2017

Change

Proper GMB Category Associations

#3

#3

-

Product/Service Keyword in GMB Business Title

#7

#7

-

Location Keyword in GMB Business Title

#17

#12

+5

Verified GMB Listing

#13

#13

-

GMB Primary Category Matches a Broader Category of the Search Category (e.g. primary category=restaurant & search=pizza)

#22

#15

+7

Age of GMB Listing

#23

#25

-2

Local Area Code on GMB Listing

#33

#32

+1

Association of Photos with GMB Listing

-

#36

+14

Matching Google Account Domain to GMB Landing Page Domain

#36

-

-14

While we did see some upward movement in the Location Keyword in GMB Business Title factor, I’m shocked to see that Product/Service Keyword in GMB Business Title did not also go up this year. It is hands-down one of the strongest factors in local pack/finder rankings. Maybe THE strongest, after Proximity of Address to the Point of Search. It seems to me that everyone and their dog is complaining about how effective this is for spammers.

Be warned: if you decide to stuff your business title with keywords, international spam hunter Joy Hawkins will probably hunt your listing down and get you penalized. :)

Also, remember what happened back when everyone was spamming links with private blog networks, and then got slapped by the Penguin Update? Google has a complete history of changes to your GMB listing, and they could decide at any time to roll out an update that will retroactively penalize your listing. Is it really worth the risk?

Age of GMB Listing might have dropped two spots, but it was ranked extremely high by Joy Hawkins and Colan Neilsen. They’re both top contributors at the Google My Business forum, and I’m not saying they know something we don’t know, but uh, maybe they know something we don’t know.

Association of Photos with GMB Listing is a factor that I’ve heard some chatter about lately. It didn’t make the top 50 in 2015, but now it’s coming in at #36. Apparently, some Google support people have said it can help your rankings. I suppose it makes sense as a quality consideration. Listings with photos might indicate a more engaged business owner. I wonder if it matters whether the photos are uploaded by the business owner, or if it’s a steady stream of incoming photo uploads from the general public to the listing. I can imagine that a business that’s regularly getting photo uploads from users might be a signal of a popular and important business.

While this factor came in as somewhat benign in the Negative Factors section (#26), No Hours of Operation on GMB Listing might be something to pay attention to, as well. Nick Neels noted in the comments:

Our data showed listings that were incomplete and missing hours of operation were highly likely to be filtered out of the results and lose visibility. As a result, we worked with our clients to gather hours for any listings missing them. Once the hours of operation were uploaded, the listings no longer were filtered.

Behavioral factors

Here are the numbers:

GMB Factors

2015

2017

Change

Clicks to Call Business

#38

#35

+3

Driving Directions to Business Clicks

#29

#43

-14

Not very exciting, but these numbers do NOT reflect the serious impact that behavioral factors are having on local search rankings and the increased impact they will have in the future. In fact, we’re never going to get numbers that truly reflect the value of behavioral factors, because many of the factors that Google has access to are inaccessible and unmeasurable by SEOs. The best place to get a sense of the impact of these factors is in the comments. When asked about what he’s seeing driving rankings this year, Phil Rozek notes:

There seem to be more “black box” ranking scenarios, which to me suggests that behavioral factors have grown in importance. What terms do people type in before clicking on you? Where do those people search from? How many customers click on you rather than on the competitor one spot above you? If Google moves you up or down in the rankings, will many people still click? I think we’re somewhere past the beginning of the era of mushy ranking factors.

Mike Blumenthal also talks about behavioral factors in his comments:

Google is in a transition period from a web-based linking approach to a knowledge graph semantic approach. As we move towards a mobile-first index, the lack of linking as a common mobile practice, voice search, and single-response answers, Google needs to and has been developing ranking factors that are not link-dependent. Content, actual in-store visitations, on-page verifiable truth, third-party validation, and news-worthiness are all becoming increasingly important.
But Google never throws anything away. Citations and links as we have known them will continue to play a part in the ranking algo, but they will be less and less important as Google increases their understanding of entity prominence and the real world.

And David Mihm says:

It’s a very difficult concept to survey about, but the overriding ranking factor in local — across both pack and organic results — is entity authority. Ask yourself, “If I were Google, how would I define a local entity, and once I did, how would I rank it relative to others?” and you’ll have the underlying algorithmic logic for at least the next decade.
  • How widely known is the entity? Especially locally, but oh man, if it’s nationally known, searchers should REALLY know about it.
  • What are people saying about the entity? (It should probably rank for similar phrases)
  • What is the engagement with the entity? Do people recognize it when they see it in search results? How many Gmail users read its newsletter? How many call or visit it after seeing it in search results? How many visit its location?

David touches on this topic in the survey response above, and then goes full BEAST MODE on the future of local rankings in his must-read post on Tidings, The Difference-Making Local Ranking Factor of 2020. (David, thank you for letting me do the Local Search Ranking Factors, but please, don’t ever leave us.)

The thing is, Google has access to so much additional data now through Chrome, Android, Maps, Ads, and Search. They’d be crazy to not use this data to help them understand which businesses are favored by real, live humans, and then rank those businesses accordingly. You can’t game this stuff, folks. In the future, my ranking advice might just be: "Be an awesome business that people like and that people interact with." Fortunately, David thinks we have until 2020 before this really sets in, so we have a few years left of keyword-stuffing business titles and building anchor text-optimized links. Phew.

To survey or to study? That is not the question

I’m a fan of Andrew Shotland’s and Dan Leibson’s Local SEO Ranking Factors Study. I think that the yearly Local Search Ranking Factors Survey and the yearly (hopefully) Local SEO Ranking Factors Study nicely complement each other. It’s great to see some hard data on what factors correlate with rankings. It confirms a lot of what the contributors to this survey are intuitively seeing impact rankings for their clients.

There are some factors that you just can’t get data for, though, and the number of these “black box” factors will continue to grow over the coming years. Factors such as:

  • Behavioral factors and entity authority, as described above. I don’t think Google is going to give SEOs this data anytime soon.
  • Relevancy. It’s tough to measure a general relevancy score for a business from all the different sources Google could be pulling this data from.
  • Even citation consistency is hard to measure. You can get a general sense of this from tools like Moz Local or Yext, but there is no single citation consistency metric you can use to score businesses by. The ecosystem is too large, too complicated, and too nuanced to get a value for consistency across all the location data that Google has access to.

The survey, on the other hand, aggregates opinions from the people that are practicing and studying local search day in and day out. They do work for clients, test things, and can see what had a positive impact on rankings and what didn’t. They can see that when they built out all of the service pages for a local home renovations company, their rankings across the board went up through increased relevancy for those terms. You can’t analyze these kinds of impacts with a quantitative study like the Local SEO Ranking Factors Study. It takes some amount of intuition and insight, and while the survey approach certainly has its flaws, it does a good job of surfacing those insights.

Going forward, I think there is great value in both the survey to get the general sense of what’s impacting rankings, and the study to back up any of our theories with data — or to potentially refute them, as they may have done with city names in webpage title tags. Andrew and Dan’s empirical study gives us more clues than we had before, so I’m looking forward to seeing what other data sources they can pull in for future editions.

Possum’s impact has been negligible

Other than Proper GMB Category Associations, which is definitely seeing a boost because of Possum, you can look at the results in this section more from the perspective of "this is what people are focusing on more IN GENERAL." Possum hasn’t made much of an impact on what we do to rank businesses in local. It has simply added another point of failure in cases where a business gets filtered.

One question that’s still outstanding in my mind is: what do you do if you are filtered? Why is one business filtered and not the other? Can you do some work to make your business rank and demote the competitor to the filter? Is it more links? More relevancy? Hopefully someone puts out some case studies soon on how to defeat the dreaded Possum filter (paging Joy Hawkins).


Focusing on More Since Possum

#1

Proximity of Address to the Point of Search

#2

Proper GMB Category Associations

#3

Quality/Authority of Inbound Links to Domain

#4

Quantity of Inbound Links to Domain from Locally Relevant Domains

#5

Click-Through Rate from Search Results


Focusing on Less Since Possum

#1

Proximity of Address to Centroid

#2

Physical Address in City of Search

#3

Proximity of Address to Centroid of Other Businesses in Industry

#4

Quantity of Structured Citations (IYPs, Data Aggregators)

#5

Consistency of Citations on Tier 3 Citation Sources


Foundational factors vs. competitive difference-makers

There are many factors in this survey that I’d consider table stakes. To get a seat at the rankings table, you must at least have these factors in order. Then there are the factors which I’d consider competitive difference-makers. These are the factors that, once you have a seat at the table, will move your rankings beyond your competitors. It’s important to note that you need BOTH. You probably won’t rank with only the foundation unless you’re in an extremely low-competition market, and you definitely won’t rank if you’re missing that foundation, no matter how many links you have.

This year I added a section to try to get a sense of what the local search experts consider foundational factors and what they consider to be competitive difference-makers. Here are the top 5 in these two categories:


Foundational

Competitive Difference Makers

#1

Proper GMB Category Associations

Quality/Authority of Inbound Links to Domain

#2

Consistency of Citations on the Primary Data Sources

Quantity of Inbound Links to Domain from Industry-Relevant Domains

#3

Physical Address in City of Search

Quality/Authority of Inbound Links to GMB Landing Page URL

#4

Proximity of Address to the Point of Search (Searcher-Business Distance)

Quantity of Inbound Links to Domain from Locally Relevant Domains

#5

Consistency of Citations on Tier 1 Citation Sources

Quantity of Native Google Reviews (with text)

I love how you can look at just these 10 factors and pretty much extract the basics of how to rank in local:

“You need to have a physical location in the city you’re trying to rank in, and it’s helpful for it to be close to the searcher. Then, make sure to have the proper categories associated with your listing, and get your citations built out and consistent on the most important sites. Now, to really move the needle, focus on getting links and reviews.”

This is the much over-simplified version, of course, so I suggest you dive into the full survey results for all the juicy details. The amount of commentary from participants is double what it was in 2015, and it’s jam-packed with nuggets of wisdom. Well worth your time.

Got your coffee? Ready to dive in?

Take a look at the full results


Sign up for The Moz Top 10, a semimonthly mailer updating you on the top ten hottest pieces of SEO news, tips, and rad links uncovered by the Moz team. Think of it as your exclusive digest of stuff you don't have time to hunt down but want to read!


from The Moz Blog http://ift.tt/2pqku68
via IFTTT

Mobile-First Indexing: Everything we know, and how it could affect you

For the past five to six months the search industry has been buzzing with talk around the biggest change to Google search results for quite some time – the mobile-first index.

In the midst of this noise, it is very easy to get lost with what you actually need to know about the update.

This post will give you a quick overview of what the update entails, as well as the main things to check for on your site to prevent a loss in traffic.

What is the Mobile-First Index?

The mobile-first index is a change in the way Google is going to index content.

Currently, Google looks at the desktop version of a site and then bases how it will rank the mobile site according to that information. Once this update rolls out, the opposite of that will happen. Google will begin looking at your mobile site and from that, will rank the desktop site.

When will it be released?

While we are still waiting for an official release date, we do know the update is in the pipeline and being tested.

Whenever Google gives us further news on when the update will be released, they repeat the message that it is still ‘months’ away. From their comments, we can assume the release is going to be in the second half of 2017.

Why is this happening?

Nearly two years ago Google announced more searches occur on mobile than desktop.

As mobile is now the predominant way for people to search on Google, it makes sense for them to ensure the experience on this device is as good as it can be.

In lots of situations, sites provide a worse or thinned down user experience on the mobile device, that is not as good as the desktop site. This happens more on mobile sites where separate URLs are used or where dynamic serving is being used.

What to check on your site

Content

Look at the mobile version of your site. Is the content from the desktop version visible/accessible? You should be providing a consistent experience for users no matter the device they access the site on.

One of the things to consider is the actual content on the site. If you are currently removing or hiding content on your mobile site, think of ways in which you can have this content on both. You ideally want content to be accessible regardless of how the site is accessed.

Make sure you also consider the best way to move this content over to the mobile site. You do not want to sacrifice your user experience just to meet this requirement.

For example, do not put a content block with 300 words of content at the top of an ecommerce category page, pushing all your products way down the page. Consider moving the content lower down the page or partially hiding it with a ‘read more’ button or in an accordion. (I’m not a big advocate of read more buttons, but do whatever works best for your site!)

Along with the actual content on the page, ensure your headings (H1s) and titles are not missing and are set as you want them to be.

Page speed

The speed of your site is an essential thing to consider to help improve usability, especially on mobile. Google already considers page speed when ranking a page, and this will be just as important when the mobile-first index is fully live.

Personally, I feel it would make more sense if this ranking factor was taken into consideration more when the mobile-first index is live. Accessing a site can be a painful experience on a mobile device when not connected to Wi-Fi, and it would make sense for Google to prioritize this usability factor more.

To check whether you need to action anything with this issue, test your site in Google’s PageSpeed Insights Tool. Alternatively, use my site speed tool of choice, GTmetrix. If any problems are shown, fix them!

If your site is not loading in around three seconds, I recommend looking into the reasons behind this and seeing why your site is slow. GTmetrix has a great Waterfall feature that is incredibly useful when trying to see which requests are slowing down your site.

Internal linking/site structure

A well-known issue with sites that use either dynamic serving or separate URLs for their mobile site is that the internal linking is vastly different to the desktop site. This can cause some user experience issues for readers as they struggle to find content that can be easily discovered on the desktop version of the site.

Similar difficulties are caused when Google crawls the mobile site. If your internal linking/information architecture on the mobile site does not closely replicate the desktop, this can cause internal link equity to be poorly distributed throughout the site, which will cause a drop in rankings.

Structured data

In a lot of cases, structured data is removed from the mobile version of the site. Unfortunately, you are going to have to move all your structured data over to the mobile site, as Google will begin looking towards that for structured data.

Use Google’s structured data testing tool on your mobile and desktop site to see if the structured data is the same across both devices.

Which sites are currently at risk?

Firebox

While the Firebox site is responsive, currently it hides content on category pages with no way to access it once you visit the mobile device. This goes against what Google is recommending. Here is an example:

New Look

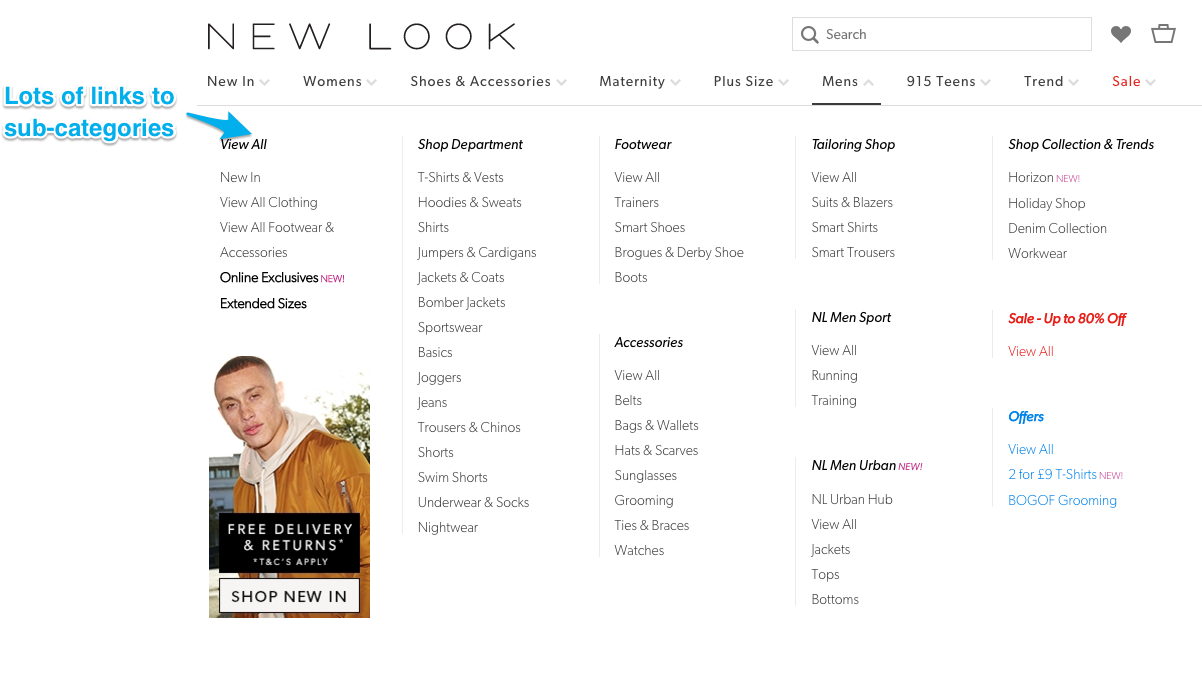
The New Look website suffers from similar issues to Firebox, except this time they are also removing internal linking along with content. See examples below:

They not only remove content from the actual main body of the page, the internal linking from the main navigation has also been reduced on mobile so it only links to the parent categories.

This is causing a large number of pages to be an increased number of clicks from the home page, which is less than ideal. See below:

There are plenty of further examples across multiple sites. Unfortunately, as Google noted in their original blog post on the mobile index, sites tend to provide vastly different content on the mobile version of their site.

While I believe that adjusting elements and the prominence of them for mobile users is something that makes sense, such as promoting search further and hiding elements in dropdowns/accordions, you need to ensure the experience is at least consistent. Avoid removing core parts of the page such as internal links and content.

A prediction for the future

Given what Google has already announced regarding the mobile index update, it is evident the main issue they are trying to tackle is poor usability of the mobile site.

Over the past year, there have been multiple updates that target sites that are ad-heavy, with low-quality content. These updates include the core/Phantom updates as well as the recently released mobile interstitial update in January.

Considering the smaller screen space on mobile, I imagine Google is only going to get more aggressive in penalizing ad heavy sites with intrusive interstitials.

I expect that future core updates will be harsher on sites that ruin the mobile experience of the site with ads. If this is something that you do, update your sites so ads are less intrusive. It’s bad for your brand, users and traffic. There is a way to implement ads without ruining your site.

To summarize

The mobile index is going to be a significant change in the way Google ranks sites. To ensure you are not negatively impacted, make sure that your user experience is similar across both the mobile and desktop site.

If you do not have a responsive site, make sure you check to see if you have any of the above issues. It may also be a good time to consider creating a responsive site to benefit from reduced maintenance.

Any questions, feel free to comment below or tweet me at @SamUnderwoodUK.


from SEO – Search Engine Watch http://ift.tt/2p1vxpG
via IFTTT

XML Sitemaps: The Most Misunderstood Tool in the SEO's Toolbox

Posted by MichaelC-15022

In all my years of SEO consulting, I’ve seen many clients with wild misconceptions about XML sitemaps. They’re a powerful tool, for sure — but like any power tool, a little training and background on how all the bits work goes a long ways.


Indexation

Probably the most common misconception is that the XML sitemap helps get your pages indexed. The first thing we’ve got to get straight is this: Google does not index your pages just because you asked nicely. Google indexes pages because (a) they found them and crawled them, and (b) they consider them good enough quality to be worth indexing. Pointing Google at a page and asking them to index it doesn’t really factor into it.

Having said that, it is important to note that by submitting an XML sitemap to Google Search Console, you’re giving Google a clue that you consider the pages in the XML sitemap to be good-quality search landing pages, worthy of indexation. But, it’s just a clue that the pages are important... like linking to a page from your main menu is.


Consistency

One of the most common mistakes I see clients make is to lack consistency in the messaging to Google about a given page. If you block a page in robots.txt and then include it in an XML sitemap, you’re being a tease. "Here, Google... a nice, juicy page you really ought to index," your sitemap says. But then your robots.txt takes it away. Same thing with meta robots: Don’t include a page in an XML sitemap and then set meta robots "noindex,follow."

While I’m at it, let me rant briefly about meta robots: "noindex" means don’t index the page. “Nofollow” means nothing about that page. It means "don’t follow the links outbound from that page," i.e. go ahead and flush all that link juice down the toilet. There’s probably some obscure reason out there for setting meta robots "noindex,nofollow," but it’s beyond me what that might be. If you want Google to not index a page, set meta robots to "noindex,follow."

OK, rant over…

In general, then, you want every page on your site to fall into two buckets:

  1. Utility pages (useful to users, but not anything you’d expect to be a search landing page)
  2. Yummy, high-quality search landing pages

Everything in bucket #1 should either be blocked by robots.txt or blocked via meta robots "noindex,follow" and should not be in an XML sitemap.

Everything in bucket #2 should not be blocked in robots.txt, should not have meta robots "noindex," and probably should be in an XML sitemap.

(Bucket image, prior to my decorating them, courtesy of Minnesota Historical Society on Flickr.)


Overall site quality

It would appear that Google is taking some measure of overall site quality, and using that site-wide metric to impact ranking — and I’m not talking about link juice here.

Think about this from Google’s perspective. Let’s say you’ve got one great page full of fabulous content that ticks all the boxes, from relevance to Panda to social media engagement. If Google sees your site as 1,000 pages of content, of which only 5–6 pages are like this one great page… well, if Google sends a user to one of those great pages, what’s the user experience going to be like if they click a link on that page and visit something else on your site? Chances are, they’re going to land on a page that sucks. It's bad UX. Why would they want to send a user to a site like that?

Google engineers certainly understand that every site has a certain number of "utility" pages that are useful to users, but not necessarily content-type pages that should be landing pages from search: pages for sharing content with others, replying to comments, logging in, retrieving a lost password, etc.

If your XML sitemap includes all of these pages, what are you communicating to Google? More or less that you have no clue as to what constitutes good content on your site and what doesn't.

Here’s the picture you want to paint for Google instead. Yes, we have a site here with 1,000 pages… and here are the 475 of those 1,000 that are our great content pages. You can ignore the others — they’re utility pages.

Now, let's say Google crawls those 475 pages, and with their metrics, decides that 175 of those are "A" grade, 200 are "B+," and 100 are "B" or "B-." That’s a pretty good overall average, and probably indicates a pretty solid site to send users to.

Contrast that with a site that submits all 1,000 pages via the XML sitemap. Now, Google looks at the 1,000 pages you say are good content, and sees over 50% are "D" or "F" pages. On average, your site is pretty sucky; Google probably doesn’t want to send users to a site like that.


The hidden fluff

Remember, Google is going to use what you submit in your XML sitemap as a clue to what's probably important on your site. But just because it's not in your XML sitemap doesn't necessarily mean that Google will ignore those pages. You could still have many thousands of pages with barely enough content and link equity to get them indexed, but really shouldn't be.

It's important to do a site: search to see all the pages that Google is indexing from your site in order to discover pages that you forgot about, and clean those out of that "average grade" Google is going to give your site by setting meta robots "noindex,follow" (or blocking in robots.txt). Generally, the weakest pages that still made the index are going to be listed last in a site: search.


Noindex vs. robots.txt

There’s an important but subtle difference between using meta robots and using robots.txt to prevent indexation of a page. Using meta robots "noindex,follow" allows the link equity going to that page to flow out to the pages it links to. If you block the page with robots.txt, you’re just flushing that down the toilet.

In the example above, I'm blocking pages that aren't real pages — they're tracking scripts — so I'm not losing link equity, as these pages DO NOT have the header with the main menu links, etc.

Think of a page like a Contact Us page, or a Privacy Policy page — probably linked to by every single page on your site via either the main menu or the footer menu. So there’s a ton of link juice going to those pages; do you just want to throw that away? Or would you rather let that link equity flow out to everything in your main menu? Easy question to answer, isn’t it?


Crawl bandwidth management

When might you actually want to use robots.txt instead? Perhaps if you’re having crawl bandwidth issues and Googlebot is spending lots of time fetching utility pages, only to discover meta robots "noindex,follow" in them and having to bail out. If you’ve got so many of these that Googlebot isn’t getting to your important pages, then you may have to block via robots.txt.

I’ve seen a number of clients see ranking improvements across the board by cleaning up their XML sitemaps and noindexing their utility pages:

Do I really have 6,000 to 20,000 pages that need crawling daily? Or is Googlebot chasing reply-to-comment or share-via-email URLs?

FYI, if you’ve got a core set of pages where content changes regularly (like a blog, new products, or product category pages) and you’ve got a ton of pages (like single product pages) where it’d be nice if Google indexed them, but not at the expense of not re-crawling and indexing the core pages, you can submit the core pages in an XML sitemap to give Google a clue that you consider them more important than the ones that aren’t blocked, but aren’t in the sitemap.


Indexation problem debugging

Here’s where the XML sitemap is really useful to SEOs: when you’re submitting a bunch of pages to Google for indexing, and only some of them are actually getting indexed. Google Search Console won’t tell you which pages they’re indexing, only an overall number indexed in each XML sitemap.

Let’s say you’re an e-commerce site and you have 100,000 product pages, 5,000 category pages, and 20,000 subcategory pages. You submit your XML sitemap of 125,000 pages, and find out that Google is indexing 87,000 of them. But which 87,000?

First off, your category and subcategory pages are probably ALL important search targets for you. I’d create a category-sitemap.xml and subcategory-sitemap.xml and submit those separately. You’re expecting to see near 100% indexation there — and if you’re not getting it, then you know you need to look at building out more content on those, increasing link juice to them, or both. You might discover something like product category or subcategory pages that aren’t getting indexed because they have only 1 product in them (or none at all) — in which case you probably want to set meta robots "noindex,follow" on those, and pull them from the XML sitemap.

Chances are, the problem lies in some of the 100,000 product pages — but which ones?

Start with a hypothesis, and split your product pages into different XML sitemaps to test those hypotheses. You can do several at once — nothing wrong with having a URL exist in multiple sitemaps.

You might start with 3 theories:

  1. Pages that don’t have a product image aren’t getting indexed
  2. Pages that have less than 200 words of unique description aren’t getting indexed
  3. Pages that don’t have comments/reviews aren’t getting indexed

Create an XML sitemap with a meaningful number of pages that fall into each of those categories. It doesn’t need to be all pages in that category — just enough that the sample size makes it reasonable to draw a conclusion based on the indexation. You might do 100 pages in each, for instance.

Your goal here is to use the overall percent indexation of any given sitemap to identify attributes of pages that are causing them to get indexed or not get indexed.

Once you know what the problem is, you can either modify the page content (or links to the pages), or noindex the pages. For example, you might have 20,000 of your 100,000 product pages where the product description is less than 50 words. If these aren’t big-traffic terms and you’re getting the descriptions from a manufacturer’s feed, it’s probably not worth your while to try and manually write additional 200 words of description for each of those 20,000 pages. You might as well set meta robots to "noindex,follow" for all pages with less than 50 words of product description, since Google isn’t going to index them anyway and they’re just bringing down your overall site quality rating. And don’t forget to remove those from your XML sitemap.


Dynamic XML sitemaps

Now you’re thinking, "OK, great, Michael. But now I’ve got to manually keep my XML sitemap in sync with my meta robots on all of my 100,000 pages," and that’s not likely to happen.

But there’s no need to do this manually. XML sitemaps don’t have to be static files. In fact, they don’t even need to have a .XML extension to submit them in Google Search Console.

Instead, set up rules logic for whether a page gets included in the XML sitemap or not, and use that same logic in the page itself to set meta robots index or noindex. That way, the moment that product description from the manufacturer’s feed gets updated by the manufacturer and goes from 42 words to 215 words, that page on your site magically shows up in the XML sitemap and gets its meta robots set to "index,follow."

On my travel website, I do this for a ton of different kinds of pages. I’m using classic ASP for those pages, so I have sitemaps like this:

When these sitemaps are fetched, instead of rendering an HTML page, the server-side code simply spits back the XML. This one iterates over a set of records from one of my database tables and spits out a record for each one that meets a certain criteria.


Video sitemaps

Oh, and what about those pesky video XML sitemaps? They're so 2015. Wistia doesn't even bother generating them anymore; you should just be using JSON-LD and http://ift.tt/yp0nX0 markup in the page itself.


Summary

  1. Be consistent — if it’s blocked in robots.txt or by meta robots "noindex," then it better not be in your XML sitemap.
  2. Use your XML sitemaps as sleuthing tools to discover and eliminate indexation problems, and only let/ask Google to index the pages you know Google is going to want to index.
  3. If you’ve got a big site, use dynamic XML sitemaps — don’t try to manually keep all this in sync between robots.txt, meta robots, and the XML sitemaps.

Cornfield image courtesy of Robert Nunnally on Flickr.


Sign up for The Moz Top 10, a semimonthly mailer updating you on the top ten hottest pieces of SEO news, tips, and rad links uncovered by the Moz team. Think of it as your exclusive digest of stuff you don't have time to hunt down but want to read!


from The Moz Blog http://ift.tt/2nXPs4z
via IFTTT

Friday, 7 April 2017

How to Use Your Competition's "Top Pages" Data to Bolster Your SEO Efforts - Whiteboard Friday

Posted by randfish

How are you gleaning your competitive insights? We've got a ton of resources and tools at our disposal, and one of the best ways to learn what's working for your rivals and how you can build your own success on top of those insights is via the top pages report. In today's Whiteboard Friday, Rand goes over how each data source can provide unique value and which questions you should be asking to get more out of that data.

Use your competition's top pages data to bolster your SEO efforts

Click on the whiteboard image above to open a high-resolution version in a new tab!

Video Transcription

Howdy, Moz fans, and welcome to another edition of Whiteboard Friday. This week we're going to chat about how you can use your competitors' top pages, data from a number of reports, from a bunch of different tools about which pages are the most important, or highest ranked, or most linked to URLs on your competitors' websites, in order to boost your SEO efforts. There's a bunch of cool things that you can do with these, beyond the obvious, and I'll walk you through a few of them today.

5 kinds of "Top Pages" reports

So first off, there are really five kinds of top pages reports. These can be further filtered and augmented with data that you could craft or create, and some of these tools add in additional data too, so you could do other things with them. But basically, these five are:

1. Top pages by links

This is essentially what are the most linked to, either by URLs, or by root domains, or highest page authority, those kinds of things. The three tools that have that are Moz, Ahrefs, and Majestic. They're the primary link tools out there on the web.

2. Top pages by social shares

This is looking at Facebook, LinkedIn, Google Plus, Twitter. Important caveat on this, Moz technically has top pages by social shares, but only from Facebook and Google Plus. Probably we'll be replacing Google Plus with LinkedIn soon. Ahrefs has it, but same story. They don't have Twitter data. BuzzSumo are the only folks who can show you Twitter data, but they only have it if they've already recorded the URL and started tracking it, because Twitter took away the ability to see Twitter share accounts for any particular URL, meaning that in order for BuzzSumo to actually get that data, they have to see that page, put it in their index, and then start collecting the tweet counts on it. So it's not perfect data, but they're certainly the best source as far as social share numbers go. You can also get some data from SharedCount.com, but it's been sort of up and down lately.

3. Top pages by estimated search traffic

So this is essentially where SEMrush shines. Ahrefs also has this. Basically, what they're doing is they're looking at, "Here all the keywords that we've seen this URL or this path or this domain ranking for, and here is the estimated keyword volume." I think both SEMrush and Ahrefs are scraping Google AdWords to collect their keyword volume data. Actually, I think maybe Ahrefs is also doing what Moz does now, where they bolster that with data that they buy from Jumpshot or possibly another clickstream provider. So essentially they're saying, "These pages are the ones we think are getting the most organic search traffic." Super valuable report from both of those guys as well.

4. Top pages by number of ranking keywords

So this is different from estimated search traffic. There could be a page on a domain that only ranks for one keyword, but it gets tons of searches and it ranks number one, so it gets an incredible amount of search traffic. But there could be pages that rank for a ton of different keywords, but they rank number 6 through 10, or they rank number 11 through 50, and they rank for all these different numbers of keywords, but none of them particularly well or none of them all that awesome, and so they don't show up in the top estimated search traffic reports. Again, SEMrush and Ahrefs provide those.

5. Top pages by total traffic

So this would be SimilarWeb and Jumpshot provide these. Alexa does too. I mean Alexa, not Amazon's voice search app, but the old Alexa rankings system. Why did they name them both the same thing? It makes it really confusing. Does it frustrate you? It frustrates me. So you can use SimilarWeb or Jumpshot to see the top pages by total traffic. So that's all sources, that's search traffic, social traffic, direct, email, links, etc., etc.

Problems to solve/questions to answer

These five I'm going to reference as we dive into problems to solve and questions to answer. But before we do that, I'm a little under the weather, so I'm going to blow my nose. I know this is unusual on Whiteboard Friday, but you don't want to see anything gnarly happening on the video. This is the proof that we only do one shot, that I really do one take.

A. What is my competition doing that's bringing them success along various vectors?

This is the most obvious one. This is the one that everybody uses the top pages reports for. So they go, "Okay, what is the most linked to? What has the most social shares?" Fine, so I can see what content has been most successful in any different one along any of those vectors. It's obvious, it's good to use, it can answer some questions, but check out these other ones.

B. Where has my competition created broad content, leaving gaps of specific queries I can fill?

Potentially fill with answer boxes, featured snippets, I could potentially fill by having a more targeted page that answers that query directly better, and so doesn't need as many links to rank, because it's very, very hyper-targeted? You can do that by looking at things that your competition has done really well on number four, top pages by number of ranking keywords, but has not done as well with total organic estimated search traffic. The gap between those two will give you those kinds of content opportunities, hyper-focused content and keyword targeting opportunities, which is killer.

C. What content has done really well, like resonated with social or direct traffic audiences, but then it's done poorly in SEO?

So, for that, I can look at number two, top pages by social shares, or number five, by total traffic, but then look at ones that have performed poorly on number of keywords and estimated search traffic.

D. What content has helped my competitors grow their link profile, but may not be ranking or maybe it used to be ranking, but it's not ranking anymore because they haven't kept the content up to date?

Maybe people were looking for stuff around 2017, and they created this content way back in 2015, and even though they got a bunch of links to it, it's just not ranking that well anymore. These are huge opportunities, and so you can look for number one being very high, high number of links, but lower number of ranking keywords and estimated search traffic.

E. What content is low on links, but high on getting search traffic and getting lots of keywords ranking for it?

Which means that there's a strong opportunity that if you can out link build them, you can probably overtake them. Because if it's weak on number of links, but it's strong on estimated search traffic and number of ranking keywords, there's probably a golden opportunity.

So you can see how by mixing and matching these things and by comparing top pages data from multiple sources against one another, you can get some really cool, powerful, advanced SEO opportunities in your content and keyword targeting.

I look forward to hearing your thoughts on this, how you've done it in the past, and we'll see you again next week for another edition of Whiteboard Friday. Take care.

Video transcription by Speechpad.com


Sign up for The Moz Top 10, a semimonthly mailer updating you on the top ten hottest pieces of SEO news, tips, and rad links uncovered by the Moz team. Think of it as your exclusive digest of stuff you don't have time to hunt down but want to read!


from The Moz Blog http://ift.tt/2nR4AS2
via IFTTT

Thursday, 6 April 2017

Grace the Stage at MozCon 2017: The Door is Open for Community Speaker Pitches

Google: Expect Conflicting Info on Mobile First Prior to Launch

Google’s Gary Illyes, speaking at Next10x yesterday, said that we can expect to hear conflicting information on the mobile first indexing change prior to its official launch and Google’s official blog post about the launch. .@methode: You will hear "conflicting information" on mobile-first until Google posts officially on the blog #Next10X — Stone Temple (@stc_corp) […]

The post Google: Expect Conflicting Info on Mobile First Prior to Launch appeared first on The SEM Post.


from The SEM Post http://ift.tt/2ngaxvF
http://ift.tt/eA8V8J via IFTTT

Google’s Mobile First Index Unlikely to Launch Before 2018

There is a little bit more breathing room for those sites needing the time to get their mobile sites ready for mobile first indexing change by Google.  It now sounds like it is unlikely to launch prior to 2018. Gary Illyes from Google commented at Next10X during his keynote that he doesn’t think it is […]

The post Google’s Mobile First Index Unlikely to Launch Before 2018 appeared first on The SEM Post.


from The SEM Post http://ift.tt/2oHxFD4
http://ift.tt/eA8V8J via IFTTT

Social Media Today